

I get asked this question more than almost any other. Usually by a manager who feels guilty for not touching a codebase in months, or by one who’s secretly still pushing PRs and wondering if that makes them a worse manager.
There are two camps, and both are loud about it.
The first camp says managers shouldn’t code at all. The moment you open an IDE, you’re stealing time from alignment, from strategy, from the things only you can do. Every hour spent debugging is an hour not spent removing blockers for twenty people.
The second camp says the opposite. If you stop coding, you lose touch with your team. You stop understanding why a deploy pipeline makes everyone want to throw their laptop out the window. You become the manager who asks “why can’t we just ship it today” without knowing what “it” actually involves anymore.
My answer is short: both extremes are wrong.
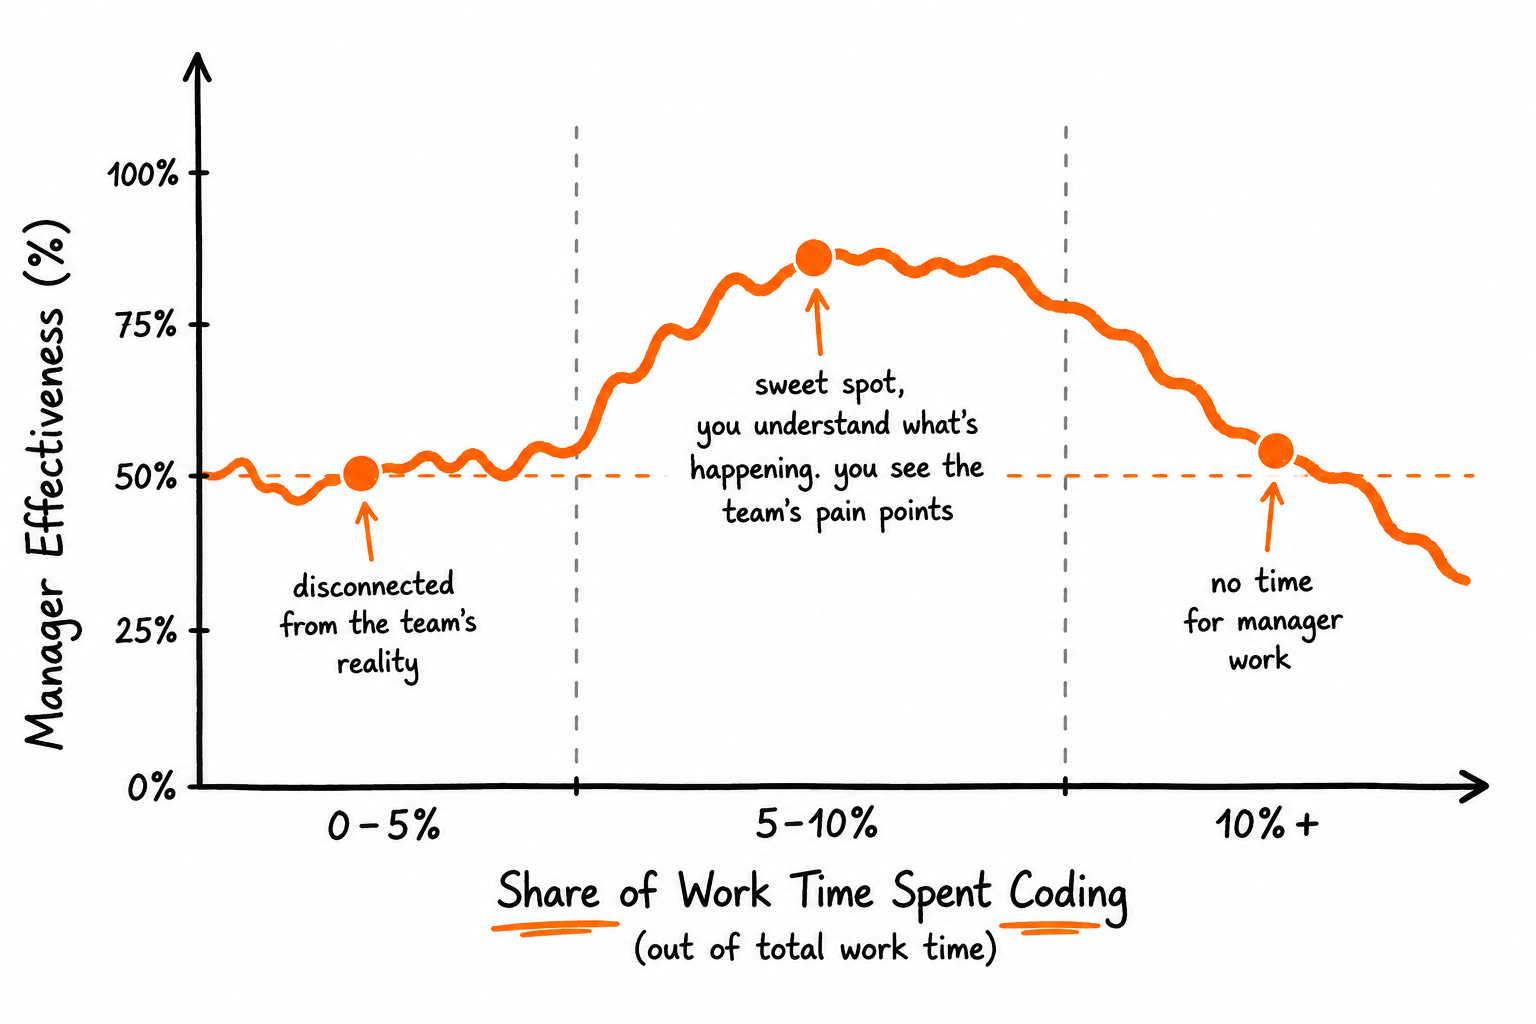
You shouldn’t be coding to ship features. That’s not your job anymore, and trying to do it on top of managing people is how you become bad at both. But you also shouldn’t disappear from the technical reality of your team completely.
The healthiest answer I’ve found sits in the middle. Spend somewhere around 5 to 10% of your working week - call it 4 hours - actually working with your team’s codebase. Not to become the tech stack expert. Not to ship the quarter’s roadmap. Just to understand what your engineers deal with every single day.
Here’s the thing nobody tells you: if you never go through the process yourself, you will never really know how painful a flaky pipeline run is. You’ll nod along when someone complains about it in standup, but you won’t feel it.
Here’s what this post covers:
How to stay technically current as a leader
How to build your own technical growth environment as a leader
My framework for working with AI
My iron rules for working with AI
1. How to stay technically current as a leader
I should tell you where I’m coming from, because it shapes everything below.
Before I became a manager, I was a full-stack PHP developer. I genuinely loved it. Then I moved into management, and like most of us, my technical knowledge started drifting further from the stack with every passing year.
Today I manage 5-6 teams, more than 20 engineers, writing in Python. A language I knew nothing about. My calendar is, to put it mildly, packed.
And yet AI made it easier for me to close that gap than it has ever been in my career.
A lot of the managers I talk to are scared off by one thing: they don’t know the tech stack their team uses, so they assume coding with them is off the table. I’d argue the opposite. Not knowing the stack isn’t a blocker anymore - it’s some cases, an advantage, because AI can translate the unfamiliar into the familiar for you.
There are three situations you’ll probably recognize yourself in:
You’re technical in the exact stack your team uses - this is the easiest case by far. AI helps you solve in one prompt what might have taken you four hours to debug solo.
You’re technical, but in a different stack - that’s me. I know PHP, I’m learning Python. This is exactly where AI is at its best: it’s a phenomenal tool for teaching you through analogy, mapping whatever’s unfamiliar back onto concepts you already understand. The specific languages barely matter - the analogy engine works for almost any pair.
You’re not technical at all - harder, but absolutely possible. You start from zero, with no bad habits to unlearn, and AI walks you through everything from scratch.
Whichever case you fall into, the goal is the same: get closer to your team, understand how they actually work day to day.
And I want to be precise about that goal, because it’s easy to drift.
Your goal here is not to deliver something for the project. Your goal is to understand how your team works and what frustrates them, technically and process-wise.
That’s the entire point of the 5-10% time block. Once you accept that, everything else in this article makes a lot more sense.
2. How to build your own technical growth environment as a leader
So how do you actually structure this, week over week, without it eating into the parts of your job that genuinely need you?
Start with how you pick your work:
No deadline attached. If something needs to ship before ~June, it’s not your task. You need slack, not pressure.
One service or one project. Don’t spread yourself across the whole codebase. Pick something narrow enough to actually learn well.
Doesn’t block anyone else. No dependencies. No release waiting on you. You should be able to merge this on your own schedule and have it just work.
No downstream consequences. A task that forces someone else to migrate a piece of infrastructure afterward is the wrong task. You want something self-contained.
Build a small backlog. A handful of tasks under one epic, ideally from the same app or service, so you’re accumulating depth instead of scattering attention. This does wonders for your own productivity too - you’re not deciding what to work on every single session, you just pull the next item off the list. Sort it from simplest to hardest and you’ve got a built-in ramp.
Block a fixed slot in your calendar. Mine is four hours, every other Friday. That lands close enough to 5-10% of my week, and because it’s recurring, it survives contact with a busy quarter.
Even on a rough week where you only get two hours instead of four, AI lets you get a surprising amount done in that window. The system holds up even when the week doesn’t cooperate.
3. My framework for working with AI
This is where it gets practical. Here’s exactly how I move from “I know nothing about this codebase” to “I just merged a real change reviewed by my team.”
Step 1: Learn the project before you touch a single task
Your biggest obstacle isn’t writing code. It’s understanding the project. This is exactly why picking tasks from one project matters - you’re not just shipping, you’re building a mental map.
Pull the repository, run git clone, and start with an AI model that’s cheap on tokens. I’m a big fan of Haiku for this specific phase - it’s extremely token-efficient, and you’re going to ask it an enormous number of questions.
Your goal here is to understand the modules, the architecture, and the technology itself. The business context you should already have as a manager - if you’re missing pieces of that too, ask about it as well. Ask the dumb questions. All of them. You need to actually understand this, not pretend to.
But watch out for one trap: there is no moment where you’ll know the project perfectly. Don’t chase that. Give yourself something like 2-4 hours of intense Q&A, then move on to an actual task. If you try to learn every single line before doing anything, you’ll loop forever and accomplish nothing.
Step 2: Run the project. Touch it. Break it a little.
Once you’ve asked your questions, the next step is simple: get the thing running. Click around the UI. Poke at it. Don’t rush.
Remember the goal isn’t delivering the task - it’s understanding the flow. So play with it.
You will hit environmental problems. Everyone does. When you do, ask AI to explain why something failed and how it fixed it, not just to fix it silently. The point of this whole exercise is learning, and a silent fix teaches you nothing.
Step 3: Take your first task and go straight to brainstorming
Grab the easiest item from the backlog you built earlier. Don’t start with implementation - start with a brainstorm on the plan, and remember the point here is learning, not shipping.
Work with AI to put together a real requirements doc first: what the task actually involves, what corner cases matter, what “done” looks like. If you already have requirements from the backlog, work from those instead.
Then ask AI to draft an implementation plan, and challenge it. Push back. Ask why it proposed building the feature inside this module instead of carving out a new one. Understanding the why behind that decision is what actually teaches you the architecture. You can even challenge the plan using a second engine - Codex challenging Claude, or vice versa - before you review it yourself.
This is a step worth turning into a Claude Code skill once you’ve done it a couple of times manually. A “brainstorm-implementation-plan” skill that knows to ask for requirements first, then a plan, then a self-challenge round, saves you from re-explaining the same process every single time.
This is also where the architecture knowledge from Step 1 actually pays off. You’re not reviewing the plan blind - you’re checking it against what you already learned about how this project is structured. A few examples of what that looks like in practice:
AI has a strong tendency toward code duplication. If the plan has you building a connector to another service, check whether that connector already exists somewhere in the codebase before writing a new one. Same logic applies to config, utility functions, anything that smells like something you saw during Step 1.
On test coverage, don’t let AI default to whatever it thinks is reasonable. Pull in your team’s actual practices and requirements - minimum coverage thresholds, whether integration tests are expected, how your team handles edge cases - and make sure the plan reflects them, not a generic standard.
If the plan proposes a new abstraction, check whether something similar already exists. You studied the modules intensively with Haiku in Step 1 specifically so you’d recognize this kind of overlap.
If naming or folder structure in the plan doesn’t match the conventions you saw elsewhere in the codebase, flag it. Consistency here is part of what makes you look like you actually understand the project, not just the task.
Once the plan holds up, hit implement. This usually takes minutes, not hours.
Step 4: Self-review - make AI explain its own feedback
Have AI review its own code. If you’re in the case where you know a different language than the one you’re working in, ask it to compare the feedback to the language you already know. I built myself a Claude skill that reviews my Python code through PHP analogies specifically, and it made everything click much faster - and once it’s a skill, it’s a one-line invocation instead of a paragraph of re-explaining every time.
The part people skip: make sure you actually understand why a piece of review feedback is a mistake, not just that it is one. After the review, run it back through a token-efficient model like Haiku and ask for a plain explanation until it actually sinks in.
Step 5: Run it, confirm it works, and open the merge request
Check that it actually works. Does something get saved? Does something fire when it should? Watch it happen, and make sure you understand it - not just that the tests pass. Only once you’re confident it works do you open the merge request.
Step 6: Team code review, then ship and repeat
This step matters even when the change is small. The point is to feel your team’s actual review process: read their comments in GitLab, see how they phrase feedback, understand the rhythm of it.
I built a second Claude skill specifically for this - “explain review” - where I feed in whatever feedback my team gives me and ask AI to translate it into a PHP analogy I already understand. That’s the third skill in this little stack: one for the brainstorm/plan stage, one for self-review, one for translating your team’s review comments.
Once the review is addressed, run the pipeline, enjoy the green checkmark, and move to your next backlog item. Some features take me two or three weeks to finish this way, spread across multiple sessions - and that’s fine. The whole point was never speed.
4. My iron rules for working with AI
A few mechanics I’ve picked up that make this whole system sustainable instead of expensive and slow.
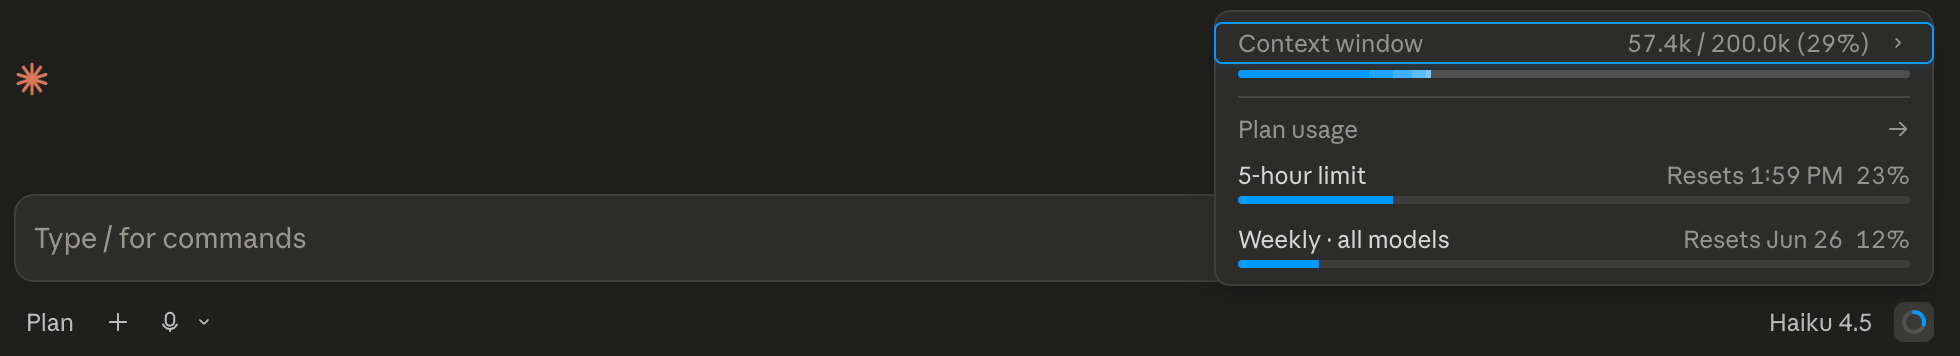
Watch your context window, and understand what’s actually happening when it fills up. This is the single most important thing in this whole section. Claude Code shows you your current context usage in the corner - a small percentage that climbs as the session goes on. That percentage isn’t just a progress bar. It’s a direct readout of how much accumulated history is sitting in your session right now: your earlier questions, intermediate code, side discussions, dead ends you explored and abandoned.
Here’s what that looks like in practice, and you’ll recognize it the first time it happens: you’ve been in the same session for a while, you tell Claude exactly what to do, in plain direct language, and it still does something dumb. Ignores half your instruction, reintroduces a bug you already fixed, forgets a decision you made twenty minutes ago. That’s not the model getting worse. That’s context rot - the session is carrying so much accumulated weight that there’s less room left to actually reason about your specific instruction. My rule: never go above 60-70% context usage. Past that threshold, code quality drops noticeably. If you’re approaching it mid-task, don’t push through. Wrap up what you can, summarize where you are, and open a new session instead.
Start a new session for every distinct task. This is the direct fix for the problem above, and it’s the one people underestimate the most. Don’t wait until you hit 70% and scramble - structure your work so you’re starting fresh by default. I run separate sessions for planning, for implementation, for requirements gathering, for review - each one isolated, each one starting clean with only the context it actually needs.
Name and archive your sessions. I name each session after what it’s doing and which feature it touches. Once it’s done, I archive it and never go back. It sounds small, but it saves a surprising amount of time you’d otherwise spend hunting through old threads.
Use the right model for the right job - and don’t assume bigger is always better. I don’t use one model for everything:
Learning and analysis → Haiku (cheap, fast, good enough for Q&A)
Planning → Sonnet
Implementation → Sonnet or Opus, depending on how complex the feature is
Review → Sonnet or Opus, same logic
Here’s the part that surprises people: the most expensive, most “powerful” model is not automatically the right choice. Opus is built for heavy, complex reasoning, and that doesn’t make it good at explaining a project to you through analogy - Haiku does that job better, and far cheaper. Same with implementation: for a genuinely simple task, Sonnet often produces a cleaner, more natural solution than Opus does. Opus tends to over-engineer simple problems, reaching for a more complicated structure than the task actually needs. If I had to pick one model to default to for most of what you’ll be doing in this flow, it’s Sonnet. It’s the most consistently useful across learning, planning, and implementation, and you only reach for Opus when the complexity of the specific feature actually calls for it.
Then, on top of that, use a token-saving plugin. I use a tool called Caveman, which compresses AI output significantly - shorthand instead of full sentences, while staying fully understandable. The headline number you’ll see floating around is a 65-75% cut in output tokens, and that part checks out: it strips filler, pleasantries, and over-explanation while keeping code and technical terms exact. Just know what that number actually covers. Output is only a slice of a real session - most of your tokens go to context, file contents, and the conversation history Claude is carrying, not to the prose it writes back to you. Once you account for that, real savings on a full session land closer to 4-10%. Worth installing anyway - it’s free, it’s a one-line setup, and shorter responses are also just faster to read. But don’t expect it to meaningfully change your bill on its own. It has no impact on code quality either way. This is a layer on top of picking the right model, not a substitute for it.
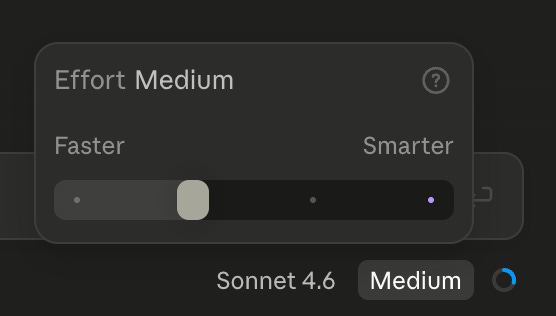
Tune the thinking effort level per model. This one’s easy to miss: Claude lets you set an effort level - low, medium, high - that controls how much it reasons before responding. I don’t leave this on the default everywhere. For Sonnet, I usually bump it from the default low up to medium, because the extra reasoning noticeably improves planning and implementation quality. For Opus, I tend to keep it at medium or even low, since Opus already reasons heavily by default and pushing it further just adds cost without much extra benefit. Worth experimenting with on your own tasks - it’s a cheap lever once you know it’s there.
The real trade-off
This doesn’t replace strategic work, and it shouldn’t try to. Five to ten percent of your week is a ceiling, not a floor you’re trying to grow. The moment this starts eating into 1-on-1s or roadmap work, you’ve lost the plot.
But the alternative - staying completely detached from your team’s day-to-day technical reality - has a cost too. You lose the ability to ask good questions in planning. You lose credibility when you push back on an estimate. You stop noticing when someone’s quietly struggling with something that should take an hour and is taking three days.
AI didn’t invent this idea. Staying hands-on as a manager has always been good practice. What AI changed is the cost of doing it. A PHP developer learning Python on a four-hour biweekly slot, with two decades less friction than it would have taken five years ago - that’s a genuinely different equation than the one we had before.
What’s your version of this? Are you coding with your team, or have you let that muscle go entirely? I’d like to know where you land.
I think it depends on the size of the team, the number of direct reports, and team seniority.
I do up to 50% coding on some weeks. Last two weeks, for example.
And sometimes I have no space for coding for a few months in a row. Hiring, upfront product planning, and compliance work take up all my time.
But often, if I didn't code, there wouldn't be much to do for me. I could finish all my week's tasks in two days and take the rest off :)